Overview
Proposed in the NanoFlow paper, overlap scheduling addresses a key bottleneck in LLM serving: the CPU overhead of scheduling, memory management, and batch preparation can leave the GPU idle between forward passes. Mini-SGLang employs overlap scheduling by default to maximize GPU utilization and minimize latency.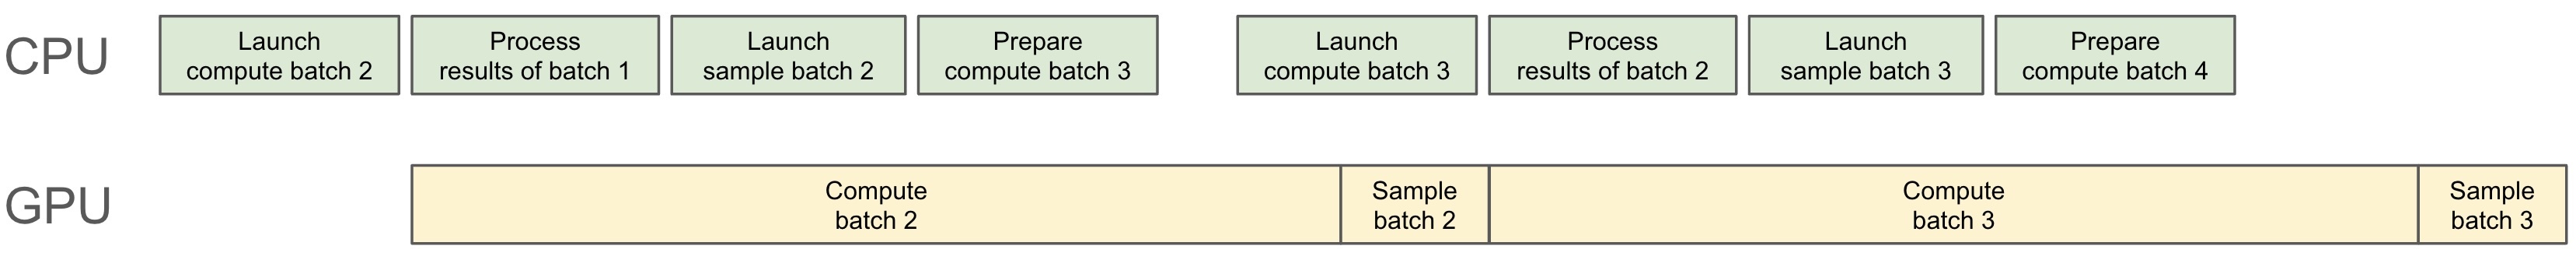 Illustration of Overlap Scheduling from LMSYS Blog
The Problem: CPU Bottleneck
Traditional Sequential Execution
Without overlap scheduling, the execution is strictly sequential:With Overlap Scheduling
Implementation
Dual Stream Architecture
Mini-SGLang uses two CUDA streams to enable overlap:- Main stream (
self.stream): Used for CPU-side operations like scheduling, memory allocation, metadata preparation - Engine stream (
self.engine.stream): Used for GPU computation (forward pass, attention, sampling)
Overlap Loop
The main event loop implements the overlap pattern:Key Insights
- Asynchronous execution: GPU work is launched asynchronously on the engine stream
- Stream synchronization:
engine.stream.wait_stream(self.stream)ensures scheduling is done before GPU starts - Overlap window: While GPU processes Batch N, CPU processes results from Batch N-1
- Data passing:
ForwardDatacaptures both input and output to be processed in the next iteration
ForwardData Structure
The overlap requires caching forward pass data:Processing Last Batch Results
While the GPU works on the current batch, the CPU processes the previous batch:- Token extraction from GPU results
- Completion detection (EOS or max length)
- Resource cleanup for finished requests
- Detokenization message sending
- Cache updates
Stream Synchronization
Wait Pattern
The synchronization ensures correct ordering:Event Synchronization
Thecopy_done event ensures GPU->CPU copies complete:
Stream synchronization is critical for correctness. The
wait_stream call ensures all scheduling work completes before GPU execution begins, while copy_done.synchronize() ensures CPU can safely read GPU results.Performance Benefits
Benchmark Results
From the Mini-SGLang README: Offline Inference Benchmark- Hardware: 1x H200 GPU
- Model: Qwen3-0.6B, Qwen3-14B
- Workload: 256 sequences, 100-1024 tokens in/out
 Overlap scheduling provides measurable throughput improvements by keeping the GPU saturated.
When Overlap Helps Most
- High CPU overhead: Complex scheduling logic, large batches, many requests
- Fast GPU execution: Small models or short sequences where CPU overhead is significant relative to GPU time
- Mixed workloads: Combination of prefill and decode requests requiring dynamic scheduling
When Overlap Helps Less
- Very large models: GPU execution dominates, little CPU time to hide
- Simple scheduling: Minimal CPU overhead leaves little to optimize
- Memory bound: If memory copies dominate, overlap may not help significantly
Disabling Overlap Scheduling
For debugging or comparison purposes, overlap scheduling can be disabled:Advanced: Extra Synchronization
For certain edge cases, additional synchronization can be enabled:Related Concepts
Architecture
Understand the scheduler’s role in the system
Chunked Prefill
See how scheduling interacts with chunked prefill
References
- NanoFlow Paper: Original proposal for overlap scheduling
- LMSYS Blog: SGLang v0.4: Detailed explanation with diagrams
- Mini-SGLang Issue #58: Discussion of synchronization edge cases