
Introduction
PageIndex is a new reasoning-based, vectorless RAG framework that performs retrieval in two steps:- Generate a tree structure index of documents
- Perform reasoning-based retrieval through tree search
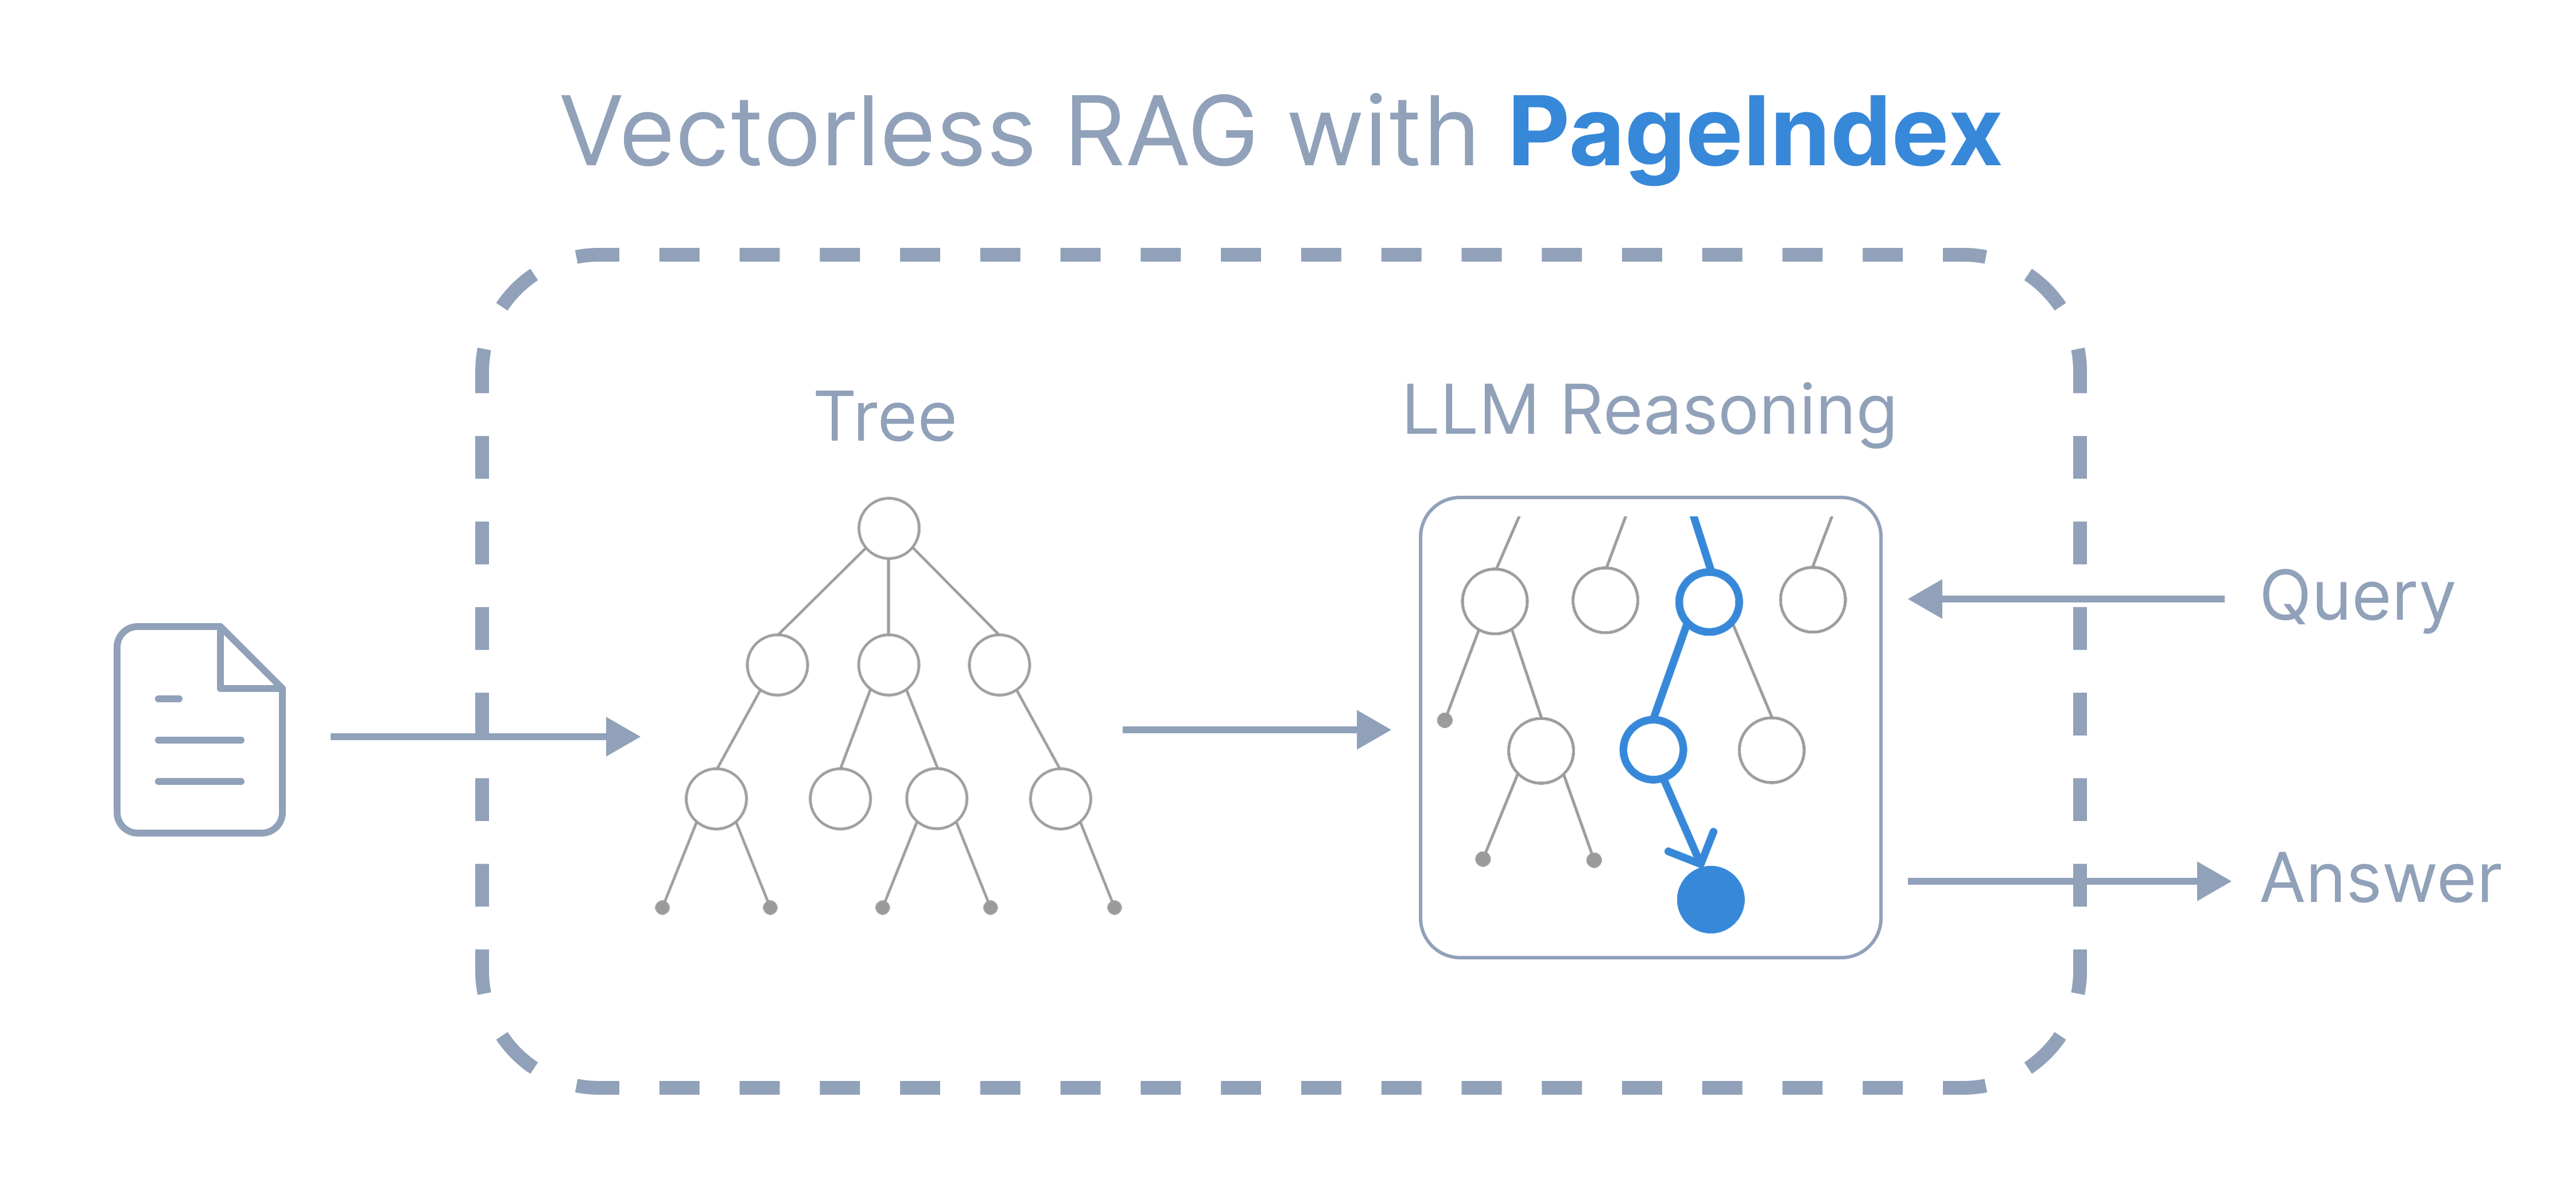 Compared to traditional vector-based RAG, PageIndex features:
- No Vectors Needed: Uses document structure and LLM reasoning for retrieval
- No Chunking Needed: Documents are organized into natural sections rather than artificial chunks
- Human-like Retrieval: Simulates how human experts navigate and extract knowledge from complex documents
- Transparent Retrieval Process: Retrieval based on reasoning — say goodbye to approximate semantic search (“vibe retrieval”)
What You’ll Learn
This cookbook demonstrates a simple, minimal example of vectorless RAG with PageIndex. You will learn how to:- Build a PageIndex tree structure of a document
- Perform reasoning-based retrieval with tree search
- Generate answers based on the retrieved context
This is a minimal example to illustrate PageIndex’s core philosophy and idea, not its full capabilities. More advanced examples are coming soon.
Setup
1
Install PageIndex
Install the PageIndex SDK:
2
Setup PageIndex Client
Initialize the PageIndex client with your API key:
3
Setup LLM
Choose your preferred LLM for reasoning-based retrieval. In this example, we use OpenAI’s GPT-4.1:
Step 1: PageIndex Tree Generation
Submit a Document
Submit a document to generate its PageIndex tree structure:Get the Tree Structure
Retrieve the generated tree structure:Step 2: Reasoning-Based Retrieval
Perform Tree Search
Use LLM for tree search to identify nodes that might contain relevant context:View Reasoning Process
Print the retrieved nodes and reasoning:Step 3: Answer Generation
Extract Context
Extract relevant content from retrieved nodes:Generate Answer
Generate an answer based on the retrieved context:What’s Next
This cookbook has demonstrated a basic, minimal example of reasoning-based, vectorless RAG with PageIndex. The workflow illustrates the core idea:Generating a hierarchical tree structure from a document, reasoning over that tree structure, and extracting relevant context, without relying on a vector database or top-k similarity search.While this cookbook highlights a minimal workflow, the PageIndex framework is built to support far more advanced use cases. In upcoming tutorials, we will introduce:
- Multi-Node Reasoning with Content Extraction — Scale tree search to extract and select relevant content from multiple nodes
- Multi-Document Search — Enable reasoning-based navigation across large document collections, extending beyond a single file
- Efficient Tree Search — Improve tree search efficiency for long documents with a large number of nodes
- Expert Knowledge Integration and Preference Alignment — Incorporate user preferences or expert insights by adding knowledge directly into the LLM tree search, without the need for fine-tuning